Abstract
Now adays people express and share their opinions on various events on the internet thanks to social media. Opinion mining is the process of interpreting user-generated opinion data on social media. Aside from its lack of resources in opinion-mining tasks, Amharic presents numerous difficulties because of its complex structure and variety of dialects. Analyzing every comment written in Amharic is a challenging task. Significant advancements in opinion mining have been achieved using deep learning. An opinion-mining model was used in this study to classify user comments written in Amharic as positive or negative. The domains that we focus on in this study are YouTube and Facebook. From the Ethiopian broadcasts YouTube and Facebook official pages, we gathered 11,872 unstructured data for this study using www.exportcomment.com, and Facebook page tools. Text preprocessing and feature extraction techniques were used, in addition to manual annotation by linguistic specialists. The dataset was prepared for the experiment after annotation, preprocessing, and representation. LSTM, GRU, BiGRU, BiLSTM, and a hybrid of CNN with BiLSTM classifiers from the TensorFlow Keras deep learning library were used to train the model using the dataset, which was split using the 80/20 train-test method, which proved effective for classification problems. Finally, we achieved of 94.27%, 95.20%, 95.49%, 95.62%, and 96.08% using GRU, BiGRU, LSTM, BiLSTM, and CNN with BiLSTM, respectively, in word2vec embedding model.
Introduction
Emperor Menelik II, the founder of modern Ethiopia, was also recognized for his strong desire to introduce contemporary technologies to the country during his reign. The modern press was first established during his leadership, with the creation of the first handwritten newspaper called Aemiro (Intelligence) in 19021. The political beliefs of the governing bodies had an impact on the evolution of the Ethiopian media. During the reign of Emperor Haile Selassie I, who succeeded Emperor Menelik II, there was a period in which the press experienced a level of growth and development. Several newspapers and magazines were also established. Radio and television were brought to the country at that time. However, the media has been criticized as a tool and supporter of the upper class2.
After the imperial regime, the country came under the control of the military regime known as Derge. The Derg regime has not experienced substantial media development. It was anticipated that all the press activities would be censored. Private media was not allowed, and all media outlets were controlled by the government, which used them as a tool to promote the socialist ideology they were advocating for3. At the beginning of the EPRDF regime in 1991, the media in Ethiopia experienced a level of freedom that had never been observed in the country’s history4. Therefore, it is possible to have dual ownership of the media, and the number of newspapers and magazines has significantly increased in the market. Nevertheless, most newspapers and magazines in the market are not successful because of issues related to professionalism, economics, and readership5.
Additionally, it is not just privately owned media that has seen improvements; media outlets owned by the government have also shown significant development6. Currently, many regional governments have their own broadcast and print media outlets. Some scholars believe that the government media does not criticize government policies and programs. However, they recognize that federal state-run radio and television have made great progress in reaching the majority of the country’s population. Similarly, private radio broadcasting has also been introduced in the country, but many have been criticized for their lack of critical programming and heavy emphasis on sensational entertainment content. Despite the fact that there have been some significant advancements in media in the country, there is still a lack of content that critiques government activities and media that truly serve the best interests of society. Knowing public opinion regarding their programs is challenging.
Sentiment analysis (opinion mining) involves the analysis and management of emotions, opinions, and subjective text content. Sentiment analysis is a method of computing and satisfying the view of a person given in a piece of text to identify people thinking about any topic as positive or negative. Sentiment analysis of social media such as Facebook and YouTube data provides an effective way to expose user opinions, which is necessary for decision-making in various fields7.
Recent advancements in deep learning have significantly enhanced opinion-mining capabilities in English. Although limited, research has been conducted to extend these methodologies to Amharic sentiment analysis. Amharic, a prominent language in Ethiopia, possesses its own distinctive written system, derived from the Ge’ez script, commonly known as Fidel. It is the second-most spoken Semitic language in the world after Arabic8 and the official working language of the Federal Democratic Republic of Ethiopia. Social media platforms have provided Internet users with a robust avenue for expressing and sharing their thoughts on various events. Among these platforms, Facebook and YouTube are the most popular for individuals to voice their opinions on a wide range of subjects. Ethiopia Broadcasting Corporation (EBC), Addis Walta, Amhara Media Corporation (AMC), Fana Broadcasting Corporation, EBS, Arts, Abbay, and Hagerie are official media services in Ethiopia covering social, economic, cultural, and political subjects. The programs are distributed on different media: television, radio, magazines, and social media sites, such as Facebook, Twitter, YouTube, and Telegram. For this study, we focused specifically on evaluating user engagement and expression across two prominent social media sites, Facebook and YouTube. The rationale behind selecting the broadcaster’s Facebook and YouTube platforms lies in their substantial membership base and the extensive availability of user-generated content. Currently, broadcasters receive comments from customers about their services through social media sites such as Facebook, Twitter, YouTube, and Telegram. The different Amharic writing styles on social media can be difficult for many reasons. Amharic has many changes in words and forms, which makes it tricky to study how its words are built. This is because the Amharic language is special. Besides not having enough resources, social media posts are often noisy. They don’t usually follow standard rules, have spelling mistakes, mixed-up writing styles, and use unusual shortcuts, which creates more problems. This study aims to design a deep learning model to automatically categorize the Amharic comments made by followers as either positive or negative. This mining or analysis was achieved by employing deep learning classifiers, specifically Long Short-Term Memory (LSTM), Gated Recurrent Units (GRU), Bidirectional Long Short-Term Memory (BiLSTM), Bidirectional Gated Recurrent Units (BiGRU), and a hybrid of a Convolutional Neural Network (CNN) and Bidirectional Long Short-Term Memory (BiLSTM). The remainder of this paper is organized as follows. The related work is revised in Section “Literature review”. Section “Proposed Model Architecture” presents the proposed method and algorithm. Section “Experiment and Results Discussion” presents experiments and discussion. Finally, Section “Conclusion and recommendation” concludes the study and outlines future work.
Literature review
In Ethiopia, the media and communication industry has undergone significant transformation over the past 30 years5. Citizens were granted relative places where they could openly express their thoughts, write, support, or oppose any position and where the constitutional system was more secure. Press freedom is also guaranteed by law and steps have been taken to maintain the media’s institutional and operational independence. According to Proclamation No. 590/2008, the current status of Ethiopian media is divided into the broadcasting media sector9. Three types of broadcasters serve the interests of local communities across the country: government-funded television and radio services controlled by national and regional media organizations or networks, private sector radio stations, and community stations. It is generally known that the number of Internet media outlets registered thus far has been minimal, and is more likely to be registered under proclamation. According to the 10 report, there are 687 media stations licensed in Ethiopia. According to the Ethiopian Broadcast Authority, there are 27 privately owned and 19 licensed public T.V. channels. More than 33 religious channels accounted for a remarkable share of the growing audience after the 2018 reforms. There are also more than 25 religion-based television channels.
Over time, broadcast and social media have come to rely on each other for engagement and content in a symbiotic relationship. Currently, social media is a significant component of broadcast media. The way media is created, shared, and consumed is evolving as a result of online resources such as Facebook, Twitter, and YouTube11. Nowadays, every broadcaster, from the BBC and ITV to less well-known networks like E Entertainment, has a YouTube presence. Many individuals who do not watch television use YouTube to view favorite shows. Facebook is the main social media network used by television shows to advertise new episodes, debuts, and the show.
The technique of identifying feelings, attitudes, and views represented in a text is called sentiment analysis and is often referred to as opinion mining. This entails determining whether the attitude expressed in the user-generated material from social media sites is negative or positive. Sentiment analysis extracts meaning from text and classifies it according to sentiment using machine learning algorithms and natural language processing (NLP) approaches12,13. Employing sentiment analysis on social media may assist organizations in several ways. This enables them to make data-driven choices, pinpoint areas for development, and obtain insightful knowledge regarding client preferences14. Businesses may improve their goods, services, and customer experiences by comprehending the mood underlying consumer evaluations and comments. In addition, sentiment research helps with crisis management, competitive analysis, and proactive customer service15. Several methods and tools are available to perform sentiment analysis efficiently. For sentiment classification, NLP libraries and frameworks, such as NLTK, SpaCy, and TensorFlow, offer pre-trained models and algorithms16. Sentiment analysis tools, including Aim Insights, Hootsuite, and Bran Watch, provide sophisticated analytics and visualization capabilities for tracking sentiment on social media17.
Inspired by artificial neural networks, Deep Learning (DL) is a burgeoning field in machine learning techniques. With the aid of the layer structure, which permits multiple processing, it provides methods for both the supervised and unsupervised learning of data representations18. The primary reason for the widespread use of deep learning techniques in sentiment analysis is their capacity for automated feature learning, which allows them to automatically identify and extract exploratory and discriminative input representations from the data. The growth of training data with multiclass classification and the effectiveness of word embeddings have further encouraged their use 19.
Deep learning includes many networks, such as Convolutional Neural Networks (CNNs), Recurrent Neural Networks (RNNs), recursive neural networks, and Deep Belief Networks (DBNs). Neural networks are beneficial for text generation, vector representation, word representation estimation, sentence classification, sentence modeling, and feature presentation20. Convolutional Neural Network (CNN) models use convolutional and pooling layers to extract high-level features. The CNN model can be constructed by applying the following steps21: The embedded words are first processed in the convolutional layer to identify features and then undergo dimensionality reduction in the pooling layer. The combined features are then passed into the fully connected layer, where the output is determined based on the sigmoid function to normalize it into two classes: positive and negative.
Owing to the unique characteristics of text context correlation, employing recurrent neural networks in text-related assignments can yield superior outcomes22. LSTM is known for its ability to effectively mitigate the problems of gradient vanishing and exploding that are frequently observed in traditional RNNs. This leads to a notable enhancement in performance compared to standard recurrent neural networks. An interesting feature of Long Short-Term Memory (LSTM) is that adjusting the input threshold, forgetting threshold, and output threshold can impact the strength of the self-circulation weight23. A previous study22proposed a sentiment classification approach based on LSTM for text data and achieved better sentiment classification performance with 85% accuracy. In the proposed study 24, sentiment analysis was performed on the Amazon Product Review dataset. A BiLSTM network was constructed and trained to classify reviews into two tiers: positive and negative. A higher accuracy of 91.4% was attained by the proposed method, which utilized the Bidirectional LSTM model. According to researchers, bidirectional long short-term memory networks can assimilate context information from both past and future inputs25. BiLSTM combines the forward hidden layer with the backward hidden layer to manipulate both previous and future inputs.
A Gated Recurrent Unit (GRU) integrates gating units to influence the information flow within the unit, effectively addressing the vanishing gradient challenge encountered in conventional Recurrent Neural Networks (RNNs). GRU is particularly advantageous for processing large volumes of text data. Similar to the Long Short-Term Memory (LSTM) model, the GRU also incorporates gating units to regulate data flow, but it differs from LSTM in that it does not require additional designated memory cells. The update and reset gates are essential elements of the GRU because they determine the information to be transmitted to the output21.The model proposed in 26 achieved an accuracy of 81% using GRU for sentiment analysis. Deep learning algorithms provide better results in text sentiment analysis and classification based on the bidirectional gated recurrent unit (GRUs) model27. The recommended model demonstrated an outstanding generalization ability and achieved a classification accuracy of 93%. It is proficient in providing precise judgments even in the presence of unfamiliar text sentiments. A multichannel LSTM-CNN model was utilized by researchers for sentiment analysis of reviews and comments from e-commerce sites. Additionally, hybrid CNN-LSTM models have been employed for the sentiment analysis of movie reviews28. According to the study, hybrid methods provide better results than single deep-learning models. In 29, new model using deep learning was suggested to analyze feelings in movie reviews from the IMDB dataset. The suggested model classifies feelings in reviews by using two Word2Vec methods: Skip Gram and Continuous Bag of Words. It works with three different sizes of word vectors: 100, 200, and 300. The best result from the proposed model was an accuracy of 95. 34%, achieved using a vector size of 300 in skip-gram embedding. The study proposed in 30 Social media sentiment analysis, uses a deep learning method and a technique called Glove for understanding word meanings. It first identifies important features with a CNN layer and then combines these features using a multi-layer bi-directional LSTM to understand long-term connections in the data. The study’s findings showed a test accuracy of 92.05%.
Proposed model architecture
The general structure of the proposed model architecture is illustrated in Fig. 1. The proposed method involves the use of LSTM, GRU, BiGRU, BiLSTM, and a hybrid of CNN and Bi-LSTM for opinion mining of Ethiopian broadcast media from Facebook and YouTube comments.

Proposed model architecture.
A. Dataset
We used www.Exportcomment.com and the Facebook page tool to extract the dataset from different Amharic news broadcast Facebook and YouTube channels, such as the Ethiopia Broadcasting Corporation (EBC), Addis Walta, Amhara Media Corporation (AMC), Fana Broadcasting Corporation, EBS, Arts, Abbay, and Hagerie, and then annotated by linguistic experts as positive or negative. The reasons for choosing Facebook and YouTube social media comments and replies are that different people write their opinions freely on these social media platforms, and users can freely express their thoughts and feelings towards the program. The number of users of social media is increasing daily, and many opinions or comments are available. Table 1 lists the social media pages used to collect the datasets. Table 2 lists the labeled dataset distributions for each proposed class.
B. Preprocessing
Data available on the Internet is not organized in a clear way. To study unorganized data, we need a way to turn it into organized data and then look at that data. NLP, Linguistic Computation, and text mining are tools used to study and get people’s opinions from different sources like comments, blogs, feedback, and reviews)31. Various language processing methods have been used to create training data with deep-learning models. Data preprocessing is an important step in creating a machine learning or deep learning model. If the data was prepared correctly, the results would be trustworthy. The first thing to do before creating a deep-learning model for language processing is to prepare the data. The preprocessing part helps to clean the input texts so they can be analyzed better32. Social media posts often have a lot of extra stuff like hashtags, codes, special symbols, and links33. Preprocessing social media texts is difficult because the content is often casual, noisy, and not well-organized. So, we should get rid of noisy and unneeded words34.To overcome these challenges, the following preprocessing techniques were used.
Tokenization is the process of separating raw data into sentences or word segments, each of which is referred to as a token35,36. In this study, we employed the Natural Language Toolkit (NLTK) package to tokenize words. This phase prevents the same word from being vectorized in several forms owing to differences in writing styles.
Stop words
The next step is to remove the stop words. Stop words are the most common words in a language and do not contribute much sense to a statement; thus, they can be removed without changing the sentence37,38.
Stemming and lemmatization
Stemming and lemmatization are the last NLP techniques used for the dataset. These two approaches are used to reduce a derived or inflected word to its root, base, or stem form38. The distinction between stemming and lemmatization is that lemmatization ensures that the root word (also known as lemma) is part of the language39.
Feature extraction
Finally, we applied text vectorization techniques, Fast Text and word2vec, to the cleaned dataset obtained after following the aforementioned steps. The process of converting preprocessed textual data into a format that the machine can understand is called word representation or text vectorization40.
C. Development Tools and Techniques
The following packages are the most widely adopted deep-learning packages in the Python system41,42.
Python
Python is a high-level programming language that supports dynamic semantics, object-oriented programming, and interpreter functionality. The deep learning approaches for this study were tested in the Jupiter Notebook editor using Python programming.
NumPy
We utilized NumPy to transform the text into numerical data to extract features and to train and test our model.
Pandas
This is a popular Python library for importing and handling the datasets.
TensorFlow
TensorFlow is commonly used in machine learning, deep learning, and numerical computation. It is an end-to-end platform that simplifies the development and deployment of deep learning models, and serves as the backend for the Keras API.
Keras
Keras significantly simplified the deep learning tasks in Python. In this study, Keras was used to create, train, store, load, and perform all the other necessary operations.
Matplotlib
Matplotlib is a plot library. This study was used to visualize YouTube user trends from the proposed class perspective and to visualize the model training history.
D. Model training and evaluation
After the data were preprocessed, they were ready to be used as inputs for deep learning algorithms. The dataset was divided into training and test sets. The training dataset consisted of 80% of the data and the test dataset consisted of 20% of the data. During the modeling process, the training dataset was divided into training and validation sets using a 0.10 (10%) validation split. The training dataset was used as input for the LSTM, Bi-LSTM, GRU, BiGRU, and a hybrid of CNN and BiLSTM deep learning algorithms. Therefore, after the models were trained, their performance was validated using the testing dataset. The following metrics were used to evaluate the performance of each model43,44.
-
Accuracy: This calculates the number of true positives out of all the data points. It is defined as true positive (TP) + true negative (TN)/TP + TN + false positive (FP) + false negative (FN).
-
Precision: This calculates the number of true positives from all input classes. It is defined as TP/TP + false negatives (FN).
-
Recall: True positives in a class are calculated from all observations in the class. It is defined as true positive (TP)/TP + false positive (FP) •.
-
F1: F1 was calculated based on precision and recall scores. It is defined as 2 × precision (P) × recall (R)/P + R.
Experiment and results discussion
-
i.
Experiment
Deep learning algorithms, particularly RNNs such as LSTM, GRU, BiGRU, and Bi-LSTM, were used in this study to perform classification. Because the results obtained using BiLSTM were higher than those of the other RNN proposed models, we applied a hybrid model with CNN, and the result obtained was the best. As the model was built, various parameters were tested, and the model with the lowest error rate or loss was chosen. As shown in Fig. 2, the accuracy of the results obtained with the hybrid CNN and BiLSTM was significantly higher than that of the bidirectional and unidirectional recurrent neural network algorithms. Experiments were carried out with different parameters for each of the selected algorithms; however, only the best strategies for preserving space were found. To summarize the results of the experiments, the hybrid CNN with the bidirectional recurrent neural model was better than the other proposed models. In addition, the bidirectional recurrent neural network produced better results than the unidirectional versions of these RNN algorithms, according to the experimental findings. Although the outcomes were different for each model, the hyperparameters, number of tests, and training datasets were identical. Table 3 summarizes the overall results of this study.

Accuracy and Loss Graph of best performing models.
-
ii.
Comparison of the proposed models with related works
The experimental results of the proposed model obtained the best results using BiLSTM with CNN, state-of-the-art models proposed in other studies in the literature, and a comparison of the accuracy results of the models are given in Table 4.Carefull and deep data preprocessing steps and using the hybrid model are the main reason to achieve the best result compared to other studies in the literature. Developing a labeled dataset for opinion mining from broadcasts social media like Facebook and YouTube, preparing a pre-trained Fast Text, Glove and word2vec word embedding model and Developing sample prototype for Amharic text opinion mining model are our main contributions.
-
iii
Results Discussion
To determine user opinions on social media platforms and to find a more effective model for categorizing comments into the suggested classes, we conducted a number of experiments. Social media followers share their thoughts on the services they receive. The intricacy of the ideas that followers on social media provide makes it difficult to discern their opinions. The conclusions of this study help us understand that user comments are more often negative than positive. This demonstrates that in order to give users a good service, broadcasters should have a system in place for users to identify their comments. To discern the polarity of the comments, four RNN models—LSTM, BiLSTM, GRU, and BiGRU— and a hybrid of CNN and BiLSTM—have been developed. For each model, we describe the classification report and accuracy in detail. As shown in Table 3, the proposed models achieved better performance. The best result was obtained in the first experiment using word2vec embedding techniques and we got we got an accuracy of 94.27%, 95.20%, 95.49%, 95.62% and 96.08% (GRU, BiGRU, LSTM, BiLSTM and CNN with BiLSTM) respectively. Furthermore, we repeated the second and third experiments using the deep learning algorithms, Glove and Fast Text, as feature extraction tools. In the second experiment using Glove as a feature extraction technique, we obtained accuracies of 93.85%, 94.65%, 95.45%, 95.58%, and 95.96% (GRU, BiGRU, LSTM, BiLSTM, and CNN with BiLSTM) respectively. In addition, we applied the third experiment using the Fast Text technique and achieved accuracies of 93.31%, 94.74%, 95.33%, 95.54%, and 95.87% (GRU, BiGRU, LSTM, BiLSTM, and CNN with BiLSTM, respectively). In comparison to the BiLSTM, LSTM BiGRU, and GRU deep learning algorithms, the hybrid CNN and BiLSTM deep learning algorithms performed better with word2vec embedding techniques because of their ability to learn both forward and backward contextual information from the text and CNN’s feature learning capability.
As per the findings of the suggested investigation, the combination of CNN and BiLSTM deep learning algorithm, along with word2vec, Glove and Fast Text embedding technique, yielded superior outcomes. This is because these feature extraction techniques can take into account various word meanings. It is important to note that the aforementioned experiments were chosen following the execution of multiple experiments with varying hyperparameters until a better-performing model was obtained. Ultimately, the models were tested with the inputs “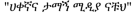 ” and “
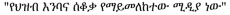 ” respectively. As shown in Fig. 3, the results were Positive and Negative.

Sample Opinion Mining System.
Conclusion and recommendation
A. Conclusion
Social media platforms, such as Facebook and YouTube, are used in broadcast media as a means of data sharing between broadcasters and their audience, in addition to providing entertainment. Social media users increase over time owing to the plethora of functions they offer, which leads to an enormous volume of public comments regarding the content they broadcast. Social media platforms are becoming increasingly popular among users of various ages. People can share their ideas, opinions, comments, and thoughts on social media sites, such as Facebook, Snapchat, YouTube, and Twitter. The vast quantities of valuable data generated and stored on social media websites are drawing the attention of researchers, business owners, and decision makers. In order to enhance goods, services, and research, opinion mining is a growing area of interest for researchers, government officials, company owners, and service providers in the field of natural language processing. As a result, there has been little research on Amharic text opinion mining of broadcast media-related Facebook and YouTube comments. Therefore, we designed and developed Amharic text opinion mining for social media related to Ethiopian broadcasters using deep learning techniques. Consequently, we gathered feedback from broadcasters on YouTube and Facebook. Then, to improve our classification model and conduct a DL algorithm experiment, extensive NLP preprocessing operations were performed. Consequently, by adjusting the classifier parameters, LSTM, BiLSTM, GRU, BiGRU, and CNN-BiLSTM hybrids were constructed. As a result, we obtained an accuracy of 95.49% using LSTM,94.27% using GRU, 95.20% using BiGRU,95.62% using BiLSTM, and 96.08% using a hybrid of CNN and BiLSTM. Overall, the findings demonstrate that the hybrid bidirectional RNN (BiLSTM) and CNN outperformed the corresponding unidirectional RNN and bidirectional algorithms in terms of accuracy. Therefore, it is more appropriate and advisable to use a bidirectional RNN with a CNN classifier for the classification of Facebook and YouTube comments. We anticipate that the findings of this study will spur broadcasters to develop the use of deep learning methods for opinion mining in relation to their offerings to improve the accessibility and acceptability of their content on social media.
B. Recommendation
Because sarcastic opinions were not included in the proposed study, they were incorrectly classified. Thus, we advise future researchers to consider these viewpoints. Additionally, more research is required regarding non-text data, such as images, emojis, and others. In this study, we gathered data solely from Facebook and YouTube, among the numerous social media platforms available today. To maximize the number of participants, future researchers could incorporate additional social media platforms. Some social media users use multiple languages to express their opinions, but this study only examines texts written in Amharic. Multilingual public opinion mining models can be created by future researchers as solutions to this constraint.
Data availability
The data that support the findings of this study are available on request from the corresponding author.
References
-
D. Bekele, “Restrictions on Press Freedom in Ethiopia: An Historical Analysis of Ethiopian Laws and Compliance with International Law,” 1–291, 2019.
-
N. A. Dodolla, “Ethiopian Media Industry Nutman Aliyi Dodolla , Addis Ababa University, Ethiopia , 2016 Abstract Background of the Study,” no. August, 2019, https://doi.org/10.13140/RG.2.2.33768.42247.
-
Kiflu, G. K. & Ali, A. C. The challenges of hosting televised deliberations in Ethiopian media. Int. J. Press. 28(1), 184–200. https://doi.org/10.1177/19401612211020267 (2023).
-
African media Initiative. 13(1), 2021. https://doi.org/10.2979/BLACKCAMERA.13.1.0299.
-
Ambelu, A. A. The development of Ethiopian media, 1991–2021. Abyssinia J. Bus. Soc. Sci. 7(1), 79–89 (2022).
-
Ross, T. J. A test of democracy: Ethiopia’s mass media and freedom of information proclamation. Penn State Law Rev. 114(3), 1047–1066 (2010).
-
P. O. Analysis, A. News, & U. Deep, “Public opinion analysis of amharic news using deep learning”.
-
Gebremedhin, G. & Mebrahtu, A. Linguistic evolution of Ethiopic languages: A comparative discussion. Int. J. Interdiscip. Res. Innov. 8(9), 1–9 (2020).
-
R. Mukundu and F. Rasmussen, “Ethiopia in transition: Hope amid challenges Ethiopia,” IMS Assess. Rep., no. October, 2018.
-
M. Alemayehu Moges, “Post-2018 media landscape in Ethiopia: A review,” 2018.
-
M. M. Asrat Seyoum; Mihret Aschalew, “Ethiopian digital media information ecosystem assessment,” Internews, 17, 2023.
-
D. Raj, “Analyzing user behavior of social media,” no. February, 11–13, 2018.
-
Zachlod, C., Samuel, O., Ochsner, A. & Werthmüller, S. Analytics of social media data – State of characteristics and application. J. Bus. Res. 144(February), 1064–1076. https://doi.org/10.1016/j.jbusres.2022.02.016 (2022).
-
Veeramani, T., Srinuvasarao, P., Rama Krishna, B. & Thilagavathy, R. Impact of social media networks big data analysis for high-level business. Int. J. Recent Technol. Eng. 7(5), 87–92 (2019).
-
S. Bhatia, J. Li, W. Peng, & T. Sun, “Monitoring and analyzing customer feedback through social media platforms for identifying and remedying customer problems,” Proc. 2013 IEEE/ACM Int. Conf. Adv. Soc. Networks Anal. Mining, ASONAM 2013, 1147–1154, 2013, https://doi.org/10.1145/2492517.2500287.
-
C. A. Dhawale & V. V. Chaudhari, “Sentiment analysis techniques, tools, applications, and challenge,” no. January 2020, 35–48, 2019, https://doi.org/10.4018/978-1-5225-8575-6.ch003.
-
Rani, S., Gill, N. S. & Gulia, P. Survey of tools and techniques for sentiment analysis of social networking data. Int. J. Adv. Comput. Sci. Appl. 12(4), 222–232. https://doi.org/10.14569/IJACSA.2021.0120430 (2021).
-
Y. Getachew, “Deep learning approach for Amharic sentiment analysis using scraped social media data,” no. November 2018, 1–9, 2023.
-
Tesfagergish, S. G., Damaševičius, R. & Kapočiūtė-Dzikienė, J. Deep learning-based sentiment classification in Amharic using multi-lingual datasets. Comput. Sci. Inf. Syst. 20(4), 1459–1481. https://doi.org/10.2298/CSIS230115042T (2023).
-
D. Endalie & G. Haile, “Automated Amharic News Categorization using deep learning models,” Comput. Intell. Neurosci., 2021, 2021, https://doi.org/10.1155/2021/3774607.
-
Alemayehu, F., Meshesha, M. & Abate, J. Amharic political sentiment analysis using deep learning approaches. Sci. Rep. 13(1), 17928. https://doi.org/10.1038/s41598-023-45137 (2023).
-
Murthy, G. S., Allu, S. R., Andhavarapu, B., Bgadi, M. & Belusonti, M. Text based sentiment analysis using long short term memory (LSTM). Int. J. Eng. Res. Technol. 9(05), 299–303 (2020).
-
M. N. A. Putera Khano, D. R. S. Saputro, S. Sutanto, & A. Wibowo, “sentiment analysis with Long-Short Term Memory (Lstm) and Gated Recurrent Unit (Gru) Algorithms,” BAREKENG J. Ilmu Mat. dan Terap., 17(4), 2235–2242, 2023, https://doi.org/10.30598/barekengvol17iss4pp2235-2242.
-
Mahadevaswamy, U. B. & Swathi, P. Sentiment analysis using bidirectional LSTM network. Procedia Comput. Sci. 218, 45–56. https://doi.org/10.1016/j.procs.2022.12.400 (2022).
-
Tan, K. L., Lee, C. P., Lim, K. M. & Anbananthen, K. S. M. Sentiment analysis with ensemble hybrid deep learning model. IEEE Access 10, 103694–103704. https://doi.org/10.1109/ACCESS.2022.3210182 (2022).
-
A. Nadeem, N. Aslam, M. K. Abid, & M. Fuzail, “Text-based sentiment analysis using CNN-GRU deep learning model,” 16–28.
-
W. Xu, J. Chen, Z. Ding, & J. Wang, “Text sentiment analysis and classification based on bidirectional Gated Recurrent Units (GRUs) model,” arXiv Prepr. arXiv2404.17123, 3–8, 2024, [Online]. Available: https://arxiv.org/abs/2404.17123
-
C. N. Dang, M. N. Moreno-García, and F. De La Prieta, “hybrid deep learning models for sentiment analysis,” Complexity, 2021, 2021, https://doi.org/10.1155/2021/9986920.
-
Başarslan, M. S. & Kayaalp, F. MBi-GRUMCONV: A novel Multi Bi-GRU and Multi CNN-Based deep learning model for social media sentiment analysis. J. Cloud Comput. 12(1), 5. https://doi.org/10.1186/s13677-022-00386-3 (2023).
-
A. Pimpalkar & J. R. Raj R, “MBiLSTMGloVe: Embedding GloVe knowledge into the corpus using multi-layer BiLSTM deep learning model for social media sentiment analysis,” Expert Syst. Appl., 203, 2022, https://doi.org/10.1016/j.eswa.2022.117581.
-
Singh, P. K., Singh, S. K. & Paul, S. Sentiment classification of social issues using contextual valence shifters. Int. J. Eng. Technol. 7(4), 1443–1452 (2015).
-
Pandey, N., Patnaik, P. K. & Gupta, S. Data pre processing for machine learning models using python libraries. Int. J. Eng. Adv. Technol. 9(4), 1995–1999. https://doi.org/10.35940/ijeat.d9057.049420 (2020).
-
S. K. Singh & M. Sachan, “Importance and challenges of social media text,” Int. J. Adv. Res. Comput. Sci., 8(3), 2015–2018, 2017, https://doi.org/10.26483/ijarcs.v8i3.3108
-
Singh, S. K. & Paul, S. Sentiment analysis of social issues and sentiment score calculation of negative prefixes. Int. J. Appl. Eng. Res. 10(55), 1694–1699 (2015).
-
E. Frank, J. Oluwaseyi, G. O. Olaoye, and G. Olaoye, “Data preprocessing techniques for NLP in BI,” no. April, 2024, [Online]. Available: https://www.researchgate.net/publication/379652291
-
Sergii, M. V. & Oleksandr, N. V. Data preprocessing and tokenization techniquesfortechnical Ukrainian texts. Appl. Asp. Inf. Technol. 6(3), 318–326 (2023).
-
Sharma, D. & Jain, S. Evaluation of stemming and stop word techniques on text classification problem. Int. J. Sci. Res. Comput. Sci. Eng. 3(2), 1–4 (2015).
-
Jakhotiya, A. et al. Text pre-processing techniques in natural language processing: A review. Int. Res. J. Eng. Technol. 09(02), 878–880 (2022).
-
Balakrishnan, V. & Lloyd-Yemoh, E. Stemming and lemmatization: A comparison of retrieval performances. Lect. Notes Softw. Eng. 2(3), 262–267 (2014).
-
K. Grzegorczyk, “Vector representations of text data in deep learning,” 2019, [Online]. Available: http://arxiv.org/abs/1901.01695
-
Mohialden, Y. M., Kadhim, R. W., Hussien, N. M. & Hussain, S. A. K. Top python-based deep learning packages: A comprehensive review. Int. J. Pap. Adv. Sci. Rev. 5(1), 1–9. https://doi.org/10.47667/ijpasr.v5i1.283 (2024).
-
Joshi, A. & Tiwari, H. An overview of python libraries for data science. J. Eng. Technol. Appl. Phys. 5(2), 85–90. https://doi.org/10.33093/jetap.2023.5.2.10 (2023).
-
Vujović, Ž. Classification model evaluation metrics. Int. J. Adv. Comput. Sci. Appl. 12(6), 599–606. https://doi.org/10.14569/IJACSA.2021.0120670 (2021).
-
Gs. Suneetha, “Classification evaluation metrics in machine learning,” 9(10), 684–687, 2022, [Online]. Available: www.jetir.orgc684
Author information
Authors and Affiliations
Contributions
Author contributions: – Problem identification and designed the analysis (Minichel Yibeyin and Yitayal Tehone); Collected the data (Yitayal Tehone and Ashagrew Liyih); Model Implementation (Minichel Yibeyin and Yitayal Tehone); Performed the result analysis (Ashagrew Liyih and Muluye Fentie); Wrote the paper (Minichel Yibeyin, Yitayal Tehone, and Muluye Fentie); Revised the paper (All authors).
Corresponding authors
Ethics declarations
Competing interests
The authors declare no competing interests.
Additional information
Publisher’s note
Springer Nature remains neutral with regard to jurisdictional claims in published maps and institutional affiliations.
Rights and permissions
Open Access This article is licensed under a Creative Commons Attribution-NonCommercial-NoDerivatives 4.0 International License, which permits any non-commercial use, sharing, distribution and reproduction in any medium or format, as long as you give appropriate credit to the original author(s) and the source, provide a link to the Creative Commons licence, and indicate if you modified the licensed material. You do not have permission under this licence to share adapted material derived from this article or parts of it. The images or other third party material in this article are included in the article’s Creative Commons licence, unless indicated otherwise in a credit line to the material. If material is not included in the article’s Creative Commons licence and your intended use is not permitted by statutory regulation or exceeds the permitted use, you will need to obtain permission directly from the copyright holder. To view a copy of this licence, visit http://creativecommons.org/licenses/by-nc-nd/4.0/.
About this article

Cite this article
Yibeyin, M., Tehone, Y., Liyih, A. et al. Public opinion mining in social media about Ethiopian broadcasts using deep learning.
Sci Rep 14, 27676 (2024). https://doi.org/10.1038/s41598-024-76542-3
-
Received:
-
Accepted:
-
Published:
-
DOI: https://doi.org/10.1038/s41598-024-76542-3
Keywords
This post was originally published on this site be sure to check out more of their content